
Building an API Integration Strategy That Actually Holds Up

An API integration strategy is the documented operating model that governs how your systems exchange data, handle failure, and evolve over time. It is not a technical diagram of which endpoints talk to which. Done right, it assigns ownership, defines data contracts, sets security rules, and gives your team a repeatable pattern for connecting new tools without breaking old ones.
If you are starting from zero, do three things this week. First, inventory every system that currently moves data in or out of your CRM, ERP, or finance stack. Second, rank your integration flows by business impact, not technical ease. Third, assign a named owner to each critical flow, someone accountable when it breaks at 2 a.m.
Here’s a starter plan you can paste into an internal memo today:
- List every system of record (CRM, ERP, HRM, e-commerce, payment processor) and who owns each one.
- Identify the three integrations that would hurt the business most if they failed tomorrow.
- Assign one accountable owner per flow, not a team, a person.
- Pick one high-value, low-complexity flow to build as your proof-of-slice, within 90 days.
- Write down your rollback plan before you write a line of integration code.
Key Takeaways
An effective API integration strategy succeeds when ownership, data contracts, and monitoring are decided before pattern selection or tool procurement.
| Point | Details |
|---|---|
| Start with ownership, not tools | Assign a named owner to each data entity before picking any integration platform. |
| Ship a proof-of-slice in 90 days | Build one high-value, low-complexity integration end to end to prove the architecture works. |
| Match pattern to flow, not habit | Use event-driven for frequent state changes, iPaaS for multiple connectors, gateways for external access. |
| Instrument before you automate | Track sync success rate, latency, and error rate from day one, not after the first incident. |
| Consider a unified platform | Manaxo combines CRM, ERP, HRM, and automation on one data model, reducing the custom integrations you need to maintain. |
Table of Contents
- What Is an API Integration Strategy, and What Happens Without One?
- How Do You Build Your API Integration Strategy, Step by Step?
- Which Integration Pattern Fits Which Flow?
- How Do You Stop Schema Drift With Data Contracts?
- How Do You Test and Roll Out Integrations Safely?
- What Should You Monitor First Once Integrations Go Live?
- Who Owns Integration Governance, and How Do You Manage Deprecation?
- Copyable API Integration Strategy Checklist
- How Do You Prove the Architecture Works in 90 Days?
- What Do Practitioners Wish They Had Known Sooner?
- An Integrated Platform Option Worth Evaluating
- Frequently Asked Questions
- Sources
What Is an API Integration Strategy, and What Happens Without One?
An API integration strategy is a set of documented rules, contracts, ownership assignments, and operating controls that govern how your systems exchange data and evolve together. It standardizes how new connections get built so you are not reinventing the wheel, and often introducing new bugs, every time someone wants system A to talk to system B.
Without one, you get a familiar mess. Point-to-point connections multiply until nobody remembers which script feeds which report. Data drifts, so your CRM says a customer has 40 open orders while your ERP says 38, and neither number is wrong exactly, just stale. Shadow APIs appear, endpoints someone spun up for a one-off project two years ago that nobody has decommissioned, and that nobody is monitoring. Ownership becomes ambiguous: when an integration fails, three teams point at each other before anyone starts debugging.
Two signals tell you this has already become a problem. If your finance team spends hours each week manually reconciling numbers between systems that are supposedly “integrated,” you have a strategy gap. If a single vendor update (a CRM field rename, an API version bump) routinely breaks two or three unrelated workflows, your architecture has no contracts protecting it from change. Both are fixable, but not by adding more point-to-point connections. That just adds more brittle joints to a structure that is already creaking.
A production-grade integration strategy needs six components: a system inventory, pattern decisions per flow, a canonical data model, a security baseline, observability with SLOs, and a documented deprecation policy. Miss any one of these and you are running an ad hoc collection of connections, not a strategy.
How Do You Build Your API Integration Strategy, Step by Step?
Building this out is not a one-week sprint, but it also should not take a year of planning before anything ships. Here is the order that works.
-
Inventory your systems and map the flows. List every application that sends or receives business data: CRM, ERP, HRM, accounting, e-commerce, payment gateway, marketing automation. For each pair that exchanges data, document direction, frequency, and volume. The artifact here is a system-of-record map, a single document showing which application owns which data entity.
-
Prioritize by impact versus complexity. Not every integration deserves equal attention. Score each flow on business impact (revenue risk, customer experience, compliance exposure) against technical complexity (number of systems touched, data sensitivity, existing tooling). The artifact is a priority matrix, usually a simple 2×2 grid that makes the argument for leadership visual and fast to grasp.
-
Decide the integration pattern per flow. A real-time inventory sync needs a different pattern than a nightly financial export. Document the choice and the reasoning in a short pattern decision memo so future engineers do not relitigate the same debate.
-
Define canonical data and contracts. Before building anything, agree on what an “Order” or a “Customer” object looks like across every system that touches it. Produce contract templates, ideally OpenAPI specs, that define the source of truth.
-
Build, test, and roll out. Develop against the contract, not against a guess. Run a full test plan before touching production traffic.
-
Operate and iterate. Once live, track your SLO dashboard daily for the first month, then weekly. Integrations are not “done” at launch; they are living systems that need scheduled review.
Your first project should be a proof-of-slice: one integration, ideally something with moderate business value and low political complexity, built end to end using this process within 90 days. Trying to redesign your entire integration landscape before shipping anything real is how these initiatives stall out in committee.
Pro Tip: Pick a slice that touches exactly two systems and one data entity, something like syncing new customer records from your web form into your CRM. It is complex enough to prove the pattern, contract, and monitoring approach work, but small enough that a failure does not take down order processing.
Which Integration Pattern Fits Which Flow?
Picking the wrong pattern is the single most common reason integrations become unmaintainable within eighteen months. Pattern choice is context-dependent: event-driven architectures suit frequent state changes, synchronous point-to-point calls work fine for simple read-heavy flows, and middleware or iPaaS earns its keep the moment a flow touches more than two or three systems.
Here are the five patterns worth knowing, and where each one belongs.
Point-to-point (direct API calls) is the fastest to build and the easiest to understand when you have two systems and a simple, low-frequency exchange. It becomes a liability the moment a third or fourth system joins the flow, because now you are maintaining N-squared connections instead of one hub.
iPaaS (integration platform as a service) centralizes connector logic and gives you prebuilt adapters for common SaaS tools. It shines when you need to stand up multiple integrations quickly and do not have deep engineering bandwidth to maintain custom code for each one.
Middleware or custom integration services make sense when your business logic is genuinely unique, transformations are complex, or you need full control over retry logic and data mapping that off-the-shelf tools cannot express.
Event-driven architecture fits flows where state changes frequently and multiple downstream systems need to react independently, think inventory updates, order status changes, or customer lifecycle events. It decouples systems so one slow consumer does not block the rest.
API gateway and management layers matter once you have external partners or multiple internal teams calling your APIs. A gateway enforces rate limits, authentication, and versioning centrally instead of leaving each team to reinvent that logic.
| Pattern | Best for | Avoid when |
|---|---|---|
| Point-to-point | Two systems, low frequency, simple payloads | More than 2-3 systems touch the same data |
| iPaaS | Multiple SaaS connectors, limited engineering time | Highly custom business logic is required |
| Middleware/custom services | Complex transformations, unique business rules | A prebuilt connector already does the job |
| Event-driven | Frequent state changes, multiple independent consumers | Simple, infrequent, one-to-one data pulls |
| API gateway | External partners, multiple internal API consumers | You have a single internal integration with no external exposure |
A practical example of misuse: a company builds five point-to-point connections between its e-commerce platform and five internal tools. Every time the e-commerce platform updates its API, all five connections need separate fixes. Switching the read-heavy, low-change flows to an event bus, and reserving point-to-point only for the one genuinely simple pair, cuts that maintenance burden dramatically.
How Do You Stop Schema Drift With Data Contracts?
Canonical data models solve a problem that sounds abstract until it costs you a week of debugging: every system has its own idea of what a “Customer” or “Order” looks like, and those definitions drift apart silently.
Define your canonical objects early: Order, Customer, Inventory Item, Invoice. For each one, specify the required fields, their types, and which system is the authoritative source. If your CRM and your ERP both store customer email addresses, decide which one wins when they disagree, and write that rule down.
A simple mapping example: your CRM’s customer.email field maps to your ERP’s client.contact_email field, and your canonical model calls it customer.primaryEmail. That mapping lives in your integration contract, not in someone’s head or a Slack thread from eight months ago.
Versioning rules prevent the contract from becoming a liability itself. Use semantic versioning for your APIs, so consumers know a major version bump means breaking changes. Set a deprecation window, 90 days is a common baseline, and require advance notice to every consumer before retiring an old version. Writing the OpenAPI spec before you write implementation code forces the contract conversation to happen up front instead of getting discovered in production.
Build automated contract validation into your CI/CD pipeline. Schema-driven tests that run on every deploy catch breaking changes before they reach a consumer, which is far cheaper than catching them after a partner’s integration silently starts failing.
How Do You Test and Roll Out Integrations Safely?
Shipping an integration without a rollout plan is how a minor bug becomes a weekend incident. Here is the sequence that keeps launches boring, in the best way.
- Test in staging with production-like volume. A flow that works fine with ten test records can choke on ten thousand real ones. Load-test before launch.
- Validate the contract automatically. Run your schema tests against the actual payloads your integration will send and receive, not just the happy-path examples.
- Check idempotency. If a request gets sent twice, whether from a retry or a duplicate webhook, the result should be identical, not a duplicate order or a double charge.
- Test edge cases deliberately. Empty fields, malformed dates, unexpected null values, and rate-limit responses all need explicit test coverage.
- Run a canary launch. Route a small percentage of real traffic through the new integration first, watch it closely, and only expand once error rates and latency look normal.
- Have a tested rollback plan ready before go-live. Not a theoretical one. Actually run the rollback in staging so you know it works when you need it under pressure.
- Build in dead-letter queues from day one. Failed messages should land somewhere reviewable and replayable, not vanish into a log file nobody checks until a customer complains.
- Add trace IDs to every request. When something breaks across three systems, a trace ID lets you follow one transaction’s path instead of guessing.
Testing idempotency, retries, and dead-letter queue behavior before launch, alongside a canary rollout and a genuine rollback plan, is what separates integrations that survive their first real incident from ones that generate a 3 a.m. page and a postmortem.
What Should You Monitor First Once Integrations Go Live?
Instrumentation decisions made in the first month determine whether your team finds out about problems from a dashboard or from an angry customer email. Start with a short list rather than trying to monitor everything at once.
Track order sync success rate, inventory accuracy percentage, webhook processing latency, API error rates by endpoint, and mean time to resolution (MTTR) when something breaks. These five metrics catch the majority of real-world integration failures before customers notice them, because monitoring order sync success and webhook latency surfaces the failure modes that hurt revenue and trust fastest.
Your runbook does not need to be elaborate. It needs three things: who gets paged when an SLO breach fires, what the first three diagnostic steps are (check the dead-letter queue, check the upstream system’s status page, check recent deploys), and when to escalate versus when to keep investigating solo. Write this down before your first incident, not during it.
Who Owns Integration Governance, and How Do You Manage Deprecation?
Ownership ambiguity kills more integrations than bad code does. Build an ownership matrix that names, for each data entity, who owns the system of record, who owns the API contract, and who owns day-to-day operations when something breaks.
- System-of-record owner: accountable for the accuracy of the data itself (e.g., the sales team owns customer records in the CRM).
- API contract owner: accountable for the schema, versioning, and breaking-change decisions.
- Operations owner: accountable for uptime, incident response, and the on-call rotation.
- Change reviewer: signs off before a contract change ships, checking downstream consumer impact first.
A deprecation policy template needs four elements: a minimum notice period (60 to 90 days is typical), migration support during that window, a firm sunset date, and a forced block at the gateway level once that date passes so a forgotten integration cannot silently keep hitting a retired endpoint.
Run a short postmortem after every integration incident, even minor ones, and require a release review before any contract change ships to production. These two habits, done consistently, are what keep an integration landscape maintainable as it grows from five connections to fifty.
Copyable API Integration Strategy Checklist
Paste this into your team’s internal wiki and score yourself honestly against each line.
- Systems of record identified: every core system has a named data owner.
- Top flows mapped and prioritized: your three highest-impact integrations are documented and ranked.
- Pattern decided per flow: each integration has a documented pattern choice with reasoning.
- Canonical data model defined: your core objects (Order, Customer, Inventory) have agreed field definitions.
- Security baseline in place: OAuth or JWT-based authentication, encryption in transit and at rest, and scoped API keys.
- Observability instrumented: sync success rate, latency, and error rate dashboards exist and someone checks them.
- SLOs written and alerting configured: thresholds exist, and alerts fire before customers notice a problem.
- Deprecation policy documented: notice periods, migration support, and sunset enforcement are written down, not assumed.
Each line has a one-sentence next action: if a box is unchecked, that is your next sprint item, not a someday project.
How Do You Prove the Architecture Works in 90 Days?
A strategy that lives only in a slide deck never gets tested until it fails in production. The fix is a tight, evidence-driven timeline.
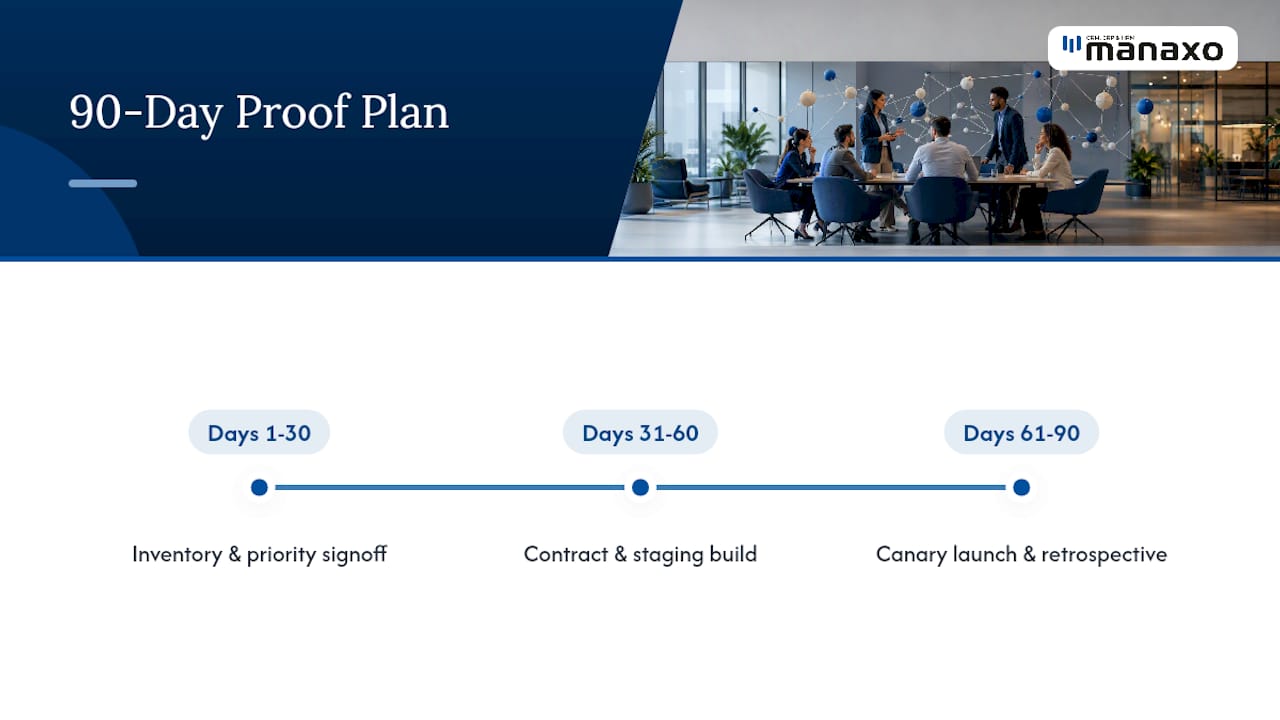
Days 1 to 30: complete the system inventory, rank your top flows, and assign owners. Deliverable: a system-of-record map and priority matrix that leadership has actually seen and signed off on.
Days 31 to 60: pick your pattern for the proof-of-slice integration, write the contract, and build it in staging. Deliverable: a working integration in a staging environment with automated contract tests passing.
Days 61 to 90: canary-launch the proof-of-slice, monitor it against your SLOs, and document what you learned. Deliverable: a production integration handling real traffic, plus a written retrospective that becomes your template for the next ten integrations.
Moving from visibility to controlled execution inside one quarter builds credibility with leadership and gives your team operational muscle they did not have before.
Security and authentication also deserve explicit attention here. Use OAuth 2.0 or JWT-based tokens for authentication rather than static API keys wherever the provider supports it, encrypt data in transit with TLS and at rest wherever it is stored, and scope every credential to the minimum access it actually needs. If your team is starting to expose integrations to AI agents, treat security scoping as a first-class design decision, not an afterthought bolted on after the agent is already live.
Design for AI-readiness from the start rather than retrofitting it. Modern integration architecture should expose actions as deterministic, discoverable, callable tools, with scoped permissions so an agent can only touch what it is explicitly allowed to touch, and full logging so every action an agent takes is auditable after the fact. This matters increasingly as businesses adopt AI tools for operational visibility: an agent that can query inventory status is useful, but only if its permissions and audit trail are as tight as a human employee’s would be.
When evaluating any platform, whether you are building custom or buying a system, judge it against four criteria: connector coverage for the tools you already use, API lifecycle support (versioning, deprecation tooling, contract testing), observability built in rather than bolted on, and a governance model that scales past a handful of integrations without requiring a dedicated integrations team. Delivery strategy also matters: productized integrations, bespoke builds, embedded workflows, and in-app agentic functionality each solve different problems, and a hybrid mix of these usually beats betting everything on one approach.
What Do Practitioners Wish They Had Known Sooner?
Start with ownership and contracts, not tools. Teams that pick a platform or a middleware product before they have named a system-of-record owner for each data entity end up automating confusion faster. Assign the owner first, define the contract second, choose the tool third.
Pick one high-value slice and prove the process before expanding. It is tempting to design the perfect end-state architecture up front, mapping every future integration before building the first one. That instinct is understandable, but it is also how these projects stall for eighteen months without shipping anything real. A single working slice, monitored and documented, teaches your team more than a year of planning documents.
The most common pitfalls repeat across companies. Teams over-automate before they have monitoring in place, so the first sign of trouble is a customer complaint rather than an alert. Schema versioning gets ignored until a vendor pushes a breaking change and three downstream systems fail simultaneously. Shadow APIs accumulate because nobody enforces a registration rule at the gateway level, so an integration built for a six-week pilot is still quietly running two years later with no owner and no monitoring.
Cross-functional alignment does not require a standing committee. A short decision meeting, thirty minutes, IT and the business owner of the affected process, before each new integration gets built, catches most scope and ownership problems before they become expensive. Pair that with a quarterly governance checkpoint to review what has shipped, what broke, and what needs deprecating, and you have most of what governance actually requires.
An Integrated Platform Option Worth Evaluating
If your integration backlog keeps growing because every new tool needs its own custom connection, the alternative is a platform where CRM, ERP, HRM, accounting, and workflow automation already share one data model. Manaxo is built this way: fewer one-off integrations to maintain because the core business systems already talk to each other, with built-in observability instead of stitching together your own monitoring stack from scratch.

When you evaluate any platform against the strategy in this guide, score it on the same criteria: how many of your existing tools does it connect to natively, does it support proper API lifecycle management with versioning and deprecation, is observability built in or something you bolt on later, and does the security baseline meet the OAuth and encryption standards this article outlines. Manaxo’s feature set covers connector coverage and automation depth worth comparing against whatever custom-built stack you are currently maintaining, and pairing it with structured CRM automation can cut the number of point-to-point connections your team is responsible for babysitting.
If the 90-day proof-of-slice approach in this guide sounds right for your team but you would rather start with a platform that already has the contracts and observability built in, check the pricing page and see whether a trial fits your current integration backlog better than another quarter of custom builds.
Frequently Asked Questions
What is the difference between an API integration and an API integration strategy?
An API integration is a single connection between two systems. An API integration strategy is the documented set of rules, ownership assignments, and patterns that govern how every integration in your organization gets built, tested, and maintained over time.
How long does it take to build an API integration strategy?
A working strategy document with ownership and priorities can come together in two to four weeks. Proving the architecture with a real production integration, the proof-of-slice, typically takes 90 days from inventory to live traffic.
What is the biggest API integration challenge for small and mid-market companies?
Ownership ambiguity, more often than technical complexity. Most integration failures trace back to nobody being clearly accountable for a data entity or a broken connection, not to a lack of engineering skill.
Do I need a dedicated integration platform, or can I build custom connections?
It depends on how many systems you are connecting and how unique your business logic is. Point-to-point connections work for one or two simple integrations. Once you are managing five or more, an iPaaS tool or a unified platform with built-in connectors usually costs less to maintain over time than custom code for each one.
How do I make my integrations ready for AI agents?
Expose your integrations as deterministic, well-documented actions with scoped permissions so an agent can only perform explicitly allowed operations, and log every action it takes for audit purposes. Treat this the same way you would treat access control for a new employee.
Sources
- API integration strategy for Shopify: A practical guide for 2026 | Shopify Enterprise
- API integration strategy: CTO guide to AI-ready systems | Agitech
- The integration strategy guide for B2B SaaS | Prismatic
Recommended


