
CRM Data Cleanup: A Practical 30/90/180-Day Playbook

Start with a baseline audit, then run the five-step hygiene framework: Audit → Dedupe → Standardize → Enrich → Govern. That sequence is the difference between a cleanup that holds and one that reverts within a quarter.
Hit those three numbers and your forecasting, lead routing, and outreach sequences become reliable. Miss them and every downstream automation compounds the error.
Here is what the timeline looks like in practice:
- 30 days: Complete the baseline audit, run a quick dedupe pass on active pipeline records, and enforce point-of-entry validation.
- 90 days: Full dedupe and standardization across all objects, enrichment for priority segments, governance policy in place.
- 180 days: Automated validation and enrichment triggers running, scheduled re-enrichment, KPIs at target levels.
One critical warning before you start: CRM data decays significantly each year. Without governance in place after the cleanup, databases often revert to a dirty state within 90 days. A one-time sprint is not enough. This playbook is built for teams who want the cleanup to stick.
Key Takeaways
Effective CRM data cleanup requires a sequenced five-step framework, realistic timeline targets, and governance that prevents decay from restarting within 90 days of the initial cleanup.
| Point | Details |
|---|---|
| Run the baseline audit first | Measure duplicate rate, fill rate, stale-record %, and bounce rate before touching any records. |
| Sequence matters: dedupe before enriching | Enriching duplicates hides them; always dedupe and standardize before spending enrichment credits. |
| Data decays at 30% per year | Without a maintenance cadence and named ownership, a cleanup reverts within 90 days. |
| Target thresholds to hit | Duplicate rate below 5%, email bounce rate below 2%, routing-field fill rate above 85%. |
| Manaxo consolidates the cleanup stack | Unified validation, enrichment triggers, and audit logs reduce decay at the point of entry. |
Table of Contents
- How to run a CRM data cleanup baseline audit
- Define governance and merge rules before writing data back
- Safe, scalable deduplication: sequence, confidence tiers, and merge rules
- Standardize and normalize key fields across your CRM
- Enrich missing fields and verify contact information efficiently
- Archive vs. delete: policy templates, criteria, and legal safeguards
- Daily, weekly, monthly, and quarterly cadence with KPIs to detect decay
- Which tools should you use for CRM data cleanup?
- A prioritized cleanup checklist with 30/90/180-day timeline
- Frequent mistakes that undo cleanups and red flags to watch for
- How an integrated platform reduces CRM decay over time
- A RevOps perspective on running a successful CRM cleanup
- Manaxo keeps your CRM data clean without the manual overhead
- Sources
How to run a CRM data cleanup baseline audit
Before you touch a single record, you need numbers. The audit tells you where the worst damage is, which objects to prioritize, and how much work you are actually looking at. Skipping this step and jumping straight to merging records is how teams accidentally destroy pipeline history.
The four reports to pull first
Run a full baseline audit covering duplicate rate, field completeness, stale-record counts, and email validity before any remediation work begins. Here is exactly what to export:
- Duplicate rate by object. Export contacts, accounts, and deals. Match on email (exact), then phone, then company name plus first/last name. Count matched pairs as a percentage of total records. A rate above 10% on contacts is a red flag requiring immediate attention.
- Field completion report. For each key field (email, phone, company, job title, lead source, lifecycle stage), calculate the percentage of records with a non-null, non-placeholder value. Pull this separately for contacts, accounts, and deals.
- Record age distribution. Bucket records by last-activity date: under 90 days, 90–180 days, 180–365 days, and over 365 days. The over-365-day bucket is your archival candidate pool.
- Email bounce and validity rate. Pull hard-bounce flags from your email platform and cross-reference with your CRM. Any contact list with a hard-bounce rate above 2% needs verification before the next send.
Baseline metrics to capture per object
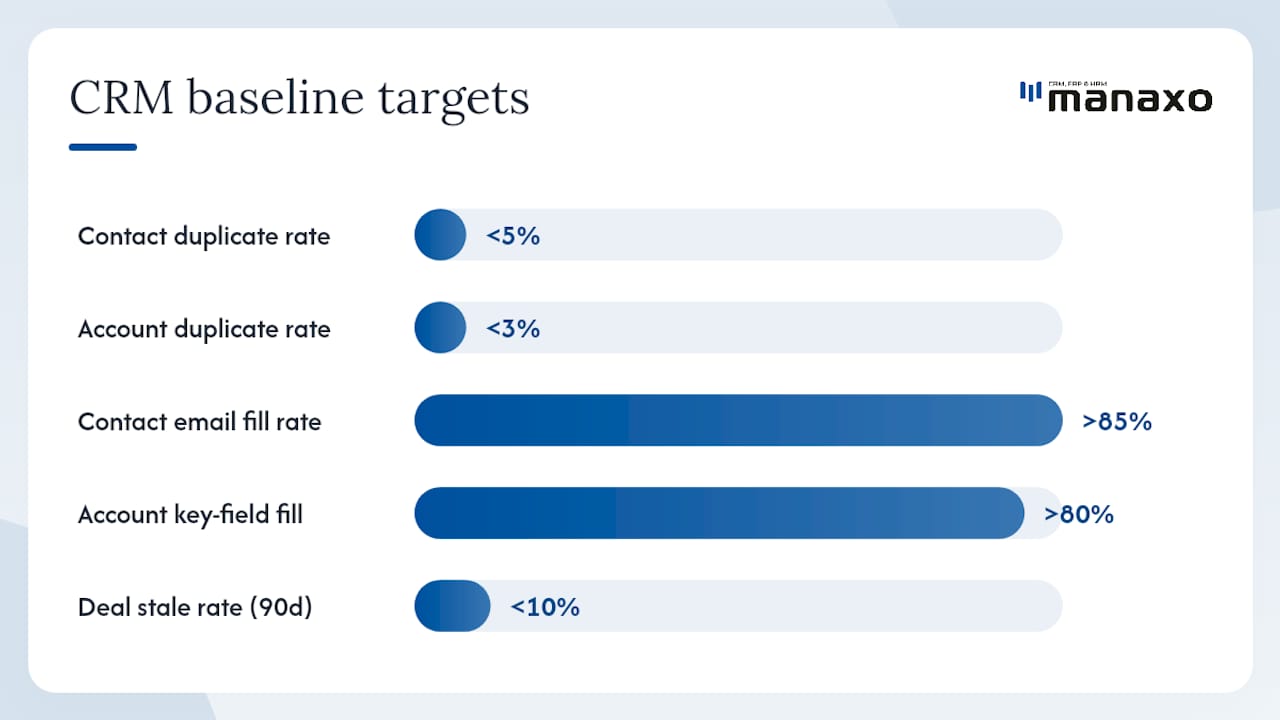
| Object | Metric | How to calculate | Target |
|---|---|---|---|
| Contact | Duplicate rate | Matched pairs / total records | < 5% |
| Contact | Email fill rate | Records with valid email / total | > 85% |
| Contact | Stale rate (365+ days) | Records with no activity in 365 days / total | < 20% |
| Account | Duplicate rate | Matched pairs / total accounts | < 3% |
| Account | Key-field fill rate | Records with industry, size, owner / total | > 80% |
| Deal | Stale deal rate | Open deals with no activity in 90 days / total open | < 10% |
Prioritization rule
Start where bad data hurts revenue most. That means active pipeline records first, then top accounts, then routing and scoring fields. A missing job title on a cold contact is a nuisance. A missing email on a deal in the proposal stage is a revenue risk. Triage accordingly.
Pro Tip: Before running any merge or write-back, export a full backup of each object to a CSV and store it outside the CRM. If something goes wrong, that file is your rollback.
Define governance and merge rules before writing data back
The most common cleanup failure mode is not bad tooling. It is teams that run a dedupe pass, merge records, and then watch the same duplicates reappear three months later because nothing changed at the point of entry. Governance is what makes the cleanup permanent.
What a data governance policy needs to cover
- Named data owner. One person is accountable for CRM data quality. Not a committee. One person with a standing weekly hygiene report in their calendar.
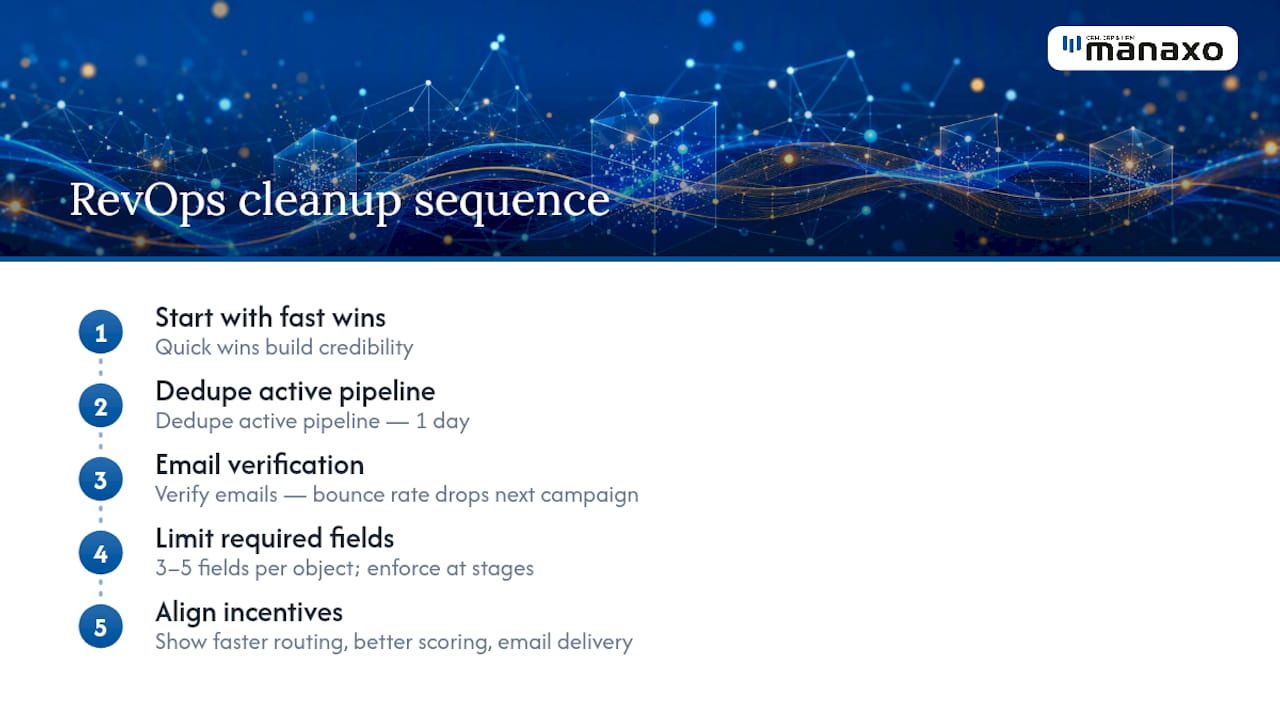
- Required fields by object. Define which fields must be populated before a record can be saved or a deal can advance to the next stage. Keep the list short: three to five fields per object. More than that and reps start entering junk values to bypass the gate.
- Acceptable values and picklists. Replace free-text fields with picklists wherever possible. Job title, industry, lead source, and lifecycle stage are the most common offenders. Free text in these fields creates hundreds of variants that are expensive to normalize later.
- Merge rules. Specify which field value wins when two records are merged. A simple rule set: most recently updated value wins for contact details; oldest value wins for create date and original source; manual review required for deal associations and activity history.
- Retention and archival policy. Define when a record moves to archived status (no activity in 12+ months, no open deals) and when it is eligible for deletion (invalid email, confirmed opt-out, no recoverable information).
- Change control. Any schema change (new field, modified picklist, changed required-field rule) requires sign-off from the data owner and a documented rollback plan.
Enforcement mechanisms that actually work
Validation rules at the field level catch bad data before it enters the system. Stage-transition required fields stop deals from advancing without the information your scoring model needs. Write-back safeguards, specifically keying every automated write by CRM record ID rather than name or email, prevent accidental overwrites on the wrong record.
Pro Tip: Add a weekly hygiene report to the data owner’s standing meeting agenda. Five minutes reviewing duplicate rate, bounce rate, and fill rate on routing fields catches drift before it becomes a cleanup project.
Safe, scalable deduplication: sequence, confidence tiers, and merge rules
Deduplicate before you enrich. Enriching duplicates can erase the signals that reveal them, making the cleanup significantly harder afterward. A contact with a patchy email and a generic job title is easy to flag as a duplicate. The same contact after enrichment looks complete and authoritative, and the merge logic misses it.
Step-by-step dedupe flow
- Exact-match on email. This is your highest-confidence tier. Two records sharing the same email address are almost certainly duplicates. Auto-merge is safe here with a preserved activity history merge.
- Phone and domain matching. Match on normalized phone number (E.164 format) or company domain. These are high-confidence but not automatic: a shared company phone number can belong to two different contacts. Queue for review rather than auto-merge.
- Fuzzy name plus company. Use fuzzy matching on first name, last name, and company name together. AI helps significantly here for fuzzy matching and anomaly detection, but never auto-merge on fuzzy matches alone. Every fuzzy match goes into a human-review queue.
- Human-review queue. Medium-confidence matches (phone/domain, fuzzy name) get reviewed by the data owner or a designated ops team member. Provide a simple interface: show both records side by side, flag the recommended winner, and require a one-click decision.
Confidence-tiered merge policy
| Confidence tier | Match criteria | Action |
|---|---|---|
| High | Exact email match | Auto-merge, preserve activity history |
| Medium | Phone/domain match or fuzzy name + company | Queue for human review within 5 business days |
| Low | Name only or partial phone | Flag as potential duplicate, no merge without manual confirmation |
Field preservation rules: The winning record keeps the most recently updated contact details. The losing record’s create date, original lead source, and all activity history are merged into the winner. Deal associations always require manual review before merge.
Pro Tip: Always run your first dedupe pass in a sandbox environment with a sample of 500–1,000 records. Check the merged output against the originals before running the full batch. One bad merge rule applied at scale is much harder to undo than one bad merge on a test set.
Standardize and normalize key fields across your CRM
Normalization is largely free. Deterministic, rule-based standardization should run before any paid enrichment or AI. Most formatting problems — inconsistent phone formats, mixed-case names, company name variants — are rule-based and fixable programmatically without spending a dollar on enrichment credits.
Fields to standardize first and the formats to adopt
- Phone numbers: E.164 format (+1XXXXXXXXXX for US numbers). Strip spaces, dashes, parentheses, and extensions into a separate field. Any number that cannot be normalized to E.164 after stripping should be flagged for verification.
- Country: ISO 3166-1 alpha-2 codes (US, CA, GB) for programmatic use, or agreed full names for display. Pick one and enforce it via picklist. “United States,” “US,” “USA,” and “U.S.A.” in the same field break every segmentation query.
- Job title: Build a canonical taxonomy with 15–25 standard values and a mapping table for variants. “VP Sales,” “Vice President of Sales,” “VP, Sales,” and “VP of Sales” all map to “VP of Sales.” Apply the mapping as a transform, not a manual edit.
- Company name: Strip legal suffixes (Inc., LLC, Corp., Ltd.) into a separate field for matching purposes, but preserve the full legal name in the display field. “Acme Inc.” and “Acme” should resolve to the same canonical account.
Rule-based tools vs. AI for normalization
Use deterministic transforms for anything with a clear rule: phone formatting, country codes, casing, suffix stripping. Use AI only for judgment calls where the rule cannot be written deterministically, such as resolving ambiguous company name variants or inferring a job title from a free-text description.
Pro Tip: Build a canonical value mapping table keyed to CRM record IDs and test your transforms on a 200-record sample before writing back at scale. If the sample output looks clean, run the full batch. If it does not, fix the rule, not the records.
Enrich missing fields and verify contact information efficiently
Enrichment comes after dedupe and standardization. Running enrichment first wastes credits on records that will be merged away, and it can obscure the duplicate signals you need. Once your records are clean and normalized, enrichment fills the gaps that matter for routing, scoring, and outreach.
Waterfall enrichment pattern
A waterfall approach runs a primary enrichment provider first, then passes unmatched or incomplete records to a secondary provider, and a tertiary provider for the remainder. This maximizes coverage without paying for redundant lookups.
- Primary provider: Highest match rate for your target segment (typically firmographic data for B2B: company size, industry, revenue range).
- Secondary provider: Fills gaps the primary missed, often stronger on direct-dial phone numbers or specific verticals.
- Tertiary provider or manual research: Reserved for high-value accounts where coverage gaps are worth the extra cost.
Prioritize verified email and direct-dial phone for outreach-sensitive records. An enriched job title is useful for scoring. A verified email is what actually gets the message delivered.
Email verification workflow
Validate emails before loading contacts into any outreach sequence. A hard-bounce rate above 2% damages sender reputation and can get your domain flagged. Run verification on any list that has not been touched in 90 days or more, and on every net-new import before the first send.
For phone numbers, normalize to E.164 first (covered in the standardization step), then run a line-type lookup to distinguish mobile from landline and flag disconnected numbers.
Re-enrichment cadence
CRM data decays significantly each year, which means a quarterly re-enrichment pass on your active contact population keeps decay manageable. High-value segments (active pipeline contacts, top accounts) warrant more frequent refreshes, monthly or after significant firmographic events like funding rounds or leadership changes.
Pro Tip: Run incremental re-enrichment on records that have changed (new import, field update, deal stage advance) rather than full-database refreshes every quarter. Incremental passes are faster, cheaper, and easier to audit.
Archive vs. delete: policy templates, criteria, and legal safeguards
The instinct to delete everything old is understandable but risky. Deletion is permanent. Archiving is reversible. For borderline records, archive first and delete only when you are certain the record is irrecoverable and compliant to remove.
Archive criteria
Archive contacts with no activity for 12 or more months and no open deals. Additional archive triggers:
- Last email bounced but contact information is otherwise complete.
- Record was imported from a list that has not been re-verified.
- Contact is at a company that has churned or gone inactive.
Archived records stay in the CRM but are excluded from active reports, routing rules, and outreach sequences. They remain searchable and can be reactivated if the contact re-engages.
Deletion criteria
Delete only when all of the following are true:
- Email is invalid and no alternative contact information exists.
- No associated deal history or revenue attribution.
- Confirmed opt-out or suppression list match.
- Retention period has expired under your data retention policy.
Compliance and legal safeguards
Before any deletion run, scrub the candidate list against your suppression list and any active opt-out records. For contacts subject to GDPR or CCPA obligations, deletion must be documented: who approved it, when it ran, and what backup exists. Keep a deletion log with record IDs, deletion date, and approver for at least 12 months after the deletion event.
Pro Tip: When in doubt, archive. A record you archive costs almost nothing in storage. A record you delete and later need for a compliance audit or a revenue attribution dispute is gone. Set a 90-day review cycle on your archive pool to catch records that have crossed the deletion threshold.
Daily, weekly, monthly, and quarterly cadence with KPIs to detect decay
A cleanup without a maintenance cadence is a project, not a program. Monthly or quarterly audits consistently outperform annual-only approaches at keeping data reliable. The cadence below is designed to catch drift early, before it compounds.
Maintenance cadence
| Frequency | Tasks | Owner |
|---|---|---|
| Daily | Validation rules fire at entry; new import quality check | Automated / CRM admin |
| Weekly | Pipeline hygiene review: stale deals, missing close dates, routing-field gaps | Data owner |
| Monthly | Dedupe run on new records, hard-bounce review, fill-rate report on key fields | Data owner + ops |
| Quarterly | Full audit (duplicate rate, stale-record %, fill rate), enrichment refresh, archive review | RevOps lead |
| Annual | Schema review: field taxonomy, picklist values, required-field rules, retention policy | Data owner + IT |
Core KPIs to track
A hygiene dashboard with completeness percentage, duplicate rate, stale-deal percentage, and next-activity coverage reviewed weekly and monthly creates the visibility and accountability that sustains hygiene. Set alert thresholds so the dashboard flags problems automatically:
- Duplicate rate: Alert if it exceeds 5% on contacts or 3% on accounts.
- Email fill rate on routing fields: Alert if it drops below 85%.
- Hard-bounce rate: Alert if it exceeds 2% after any send.
- Stale-record percentage: Alert if records with no activity in 180 days exceed 25% of the active contact population.
Reporting impact to leadership
Before-and-after metrics are the clearest way to show the value of the cleanup program. Track duplicate rate, bounce rate, and fill rate at the start of the cleanup and report the delta at 30, 90, and 180 days. Pair those numbers with pipeline metrics: routing accuracy, sequence deliverability, and forecast reliability. Those are the numbers leadership cares about.
Which tools should you use for CRM data cleanup?
The right tool stack depends on record volume, object complexity, and how much of the process you want to automate. Native CRM features handle a surprising amount of the work at smaller scale. Third-party tooling earns its cost when volume, multi-object dedupe, or enrichment coverage requirements exceed what native tools can deliver.
Tool categories and what each one does
- Native CRM dedupe tools. Most major CRMs include basic duplicate detection on contacts and accounts. Run these first before evaluating third-party options. They are free, already integrated, and sufficient for databases under 10,000 records with straightforward matching needs.
- Dedicated deduplication tools. Purpose-built dedupe platforms handle fuzzy matching across multiple objects, confidence scoring, and merge-rule configuration at scale. Worth evaluating when your duplicate rate is high, your record volume is large, or you need multi-object dedupe (contacts linked to accounts linked to deals).
- Enrichment providers. B2B data providers supply firmographic and contact data to fill gaps. Evaluate on match rate for your target segment, data freshness, and cost per enrichment. Waterfall enrichment across two or three providers typically outperforms any single provider on coverage.
- Email and phone validation services. Standalone validation services verify deliverability and line type before outreach. Run these as a pre-send gate, not just during cleanup.
- Orchestration and automation platforms. Workflow automation tools connect enrichment, validation, and write-back steps into a triggered pipeline. These reduce manual work significantly once the initial cleanup is complete.
Decision criteria by scale
For databases under 10,000 records, native CRM features plus a validation service and one enrichment provider cover most needs. For 10,000–50,000 records, add a dedicated dedupe tool and consider a waterfall enrichment setup. Above 50,000 records, an orchestration layer that automates the full pipeline (validate on entry, enrich on trigger, dedupe on schedule) is worth the investment.
Pro Tip: Prefer tools that support API-driven waterfall enrichment and expose audit logs for every merge and write-back. If you cannot see what changed, when, and why, you cannot debug problems or demonstrate compliance.
A prioritized cleanup checklist with 30/90/180-day timeline
This is the plan you can hand to your team on Monday. Effort estimates assume a named data owner plus part-time ops support.
30-day sprint
- Export full backups of contacts, accounts, and deals to CSV.
- Run the baseline audit: duplicate rate, fill rate, stale-record distribution, bounce rate.
- Dedupe active pipeline contacts and accounts using native CRM tools (exact-match email first).
- Enforce point-of-entry validation rules on required fields for new records.
- Flag hard-bounce contacts and remove from active sequences.
Effort estimate: Small database (under 10,000 records): 20–30 hours. Medium (10,000–50,000 records): 40–60 hours. Large (over 50,000 records): 80–120 hours with dedicated RevOps resource.
90-day plan
- Complete a full dedupe pass across all objects using the confidence-tiered merge policy.
- Run standardization transforms on phone, country, job title, and company name fields.
- Enrich priority segments (active pipeline, top accounts) using a waterfall enrichment setup.
- Establish the governance policy: named owner, required fields, picklists, merge rules, retention policy.
- Launch the weekly hygiene report and assign it to the data owner.
180-day goals
- Automated validation triggers running on every inbound record (form fill, import, API write).
- Enrichment triggers firing on new records and on deal-stage advances for high-value contacts.
- Quarterly re-enrichment scheduled for the full active contact population.
- KPIs at target: duplicate rate below 5%, bounce rate below 2%, fill rate above 85% on routing fields.
- Archive pass completed on records with no activity in 12 or more months.
Frequent mistakes that undo cleanups and red flags to watch for
Most cleanup failures are not technical. They are sequencing errors, missing safeguards, or governance gaps that let the same problems reappear.
Common pitfalls
- Enriching before deduplicating. Enriched duplicates look complete and authoritative, which makes them harder to detect and merge correctly. Always dedupe first.
- Writing back without keying by record ID. Matching write-backs on name or email instead of the CRM’s unique record ID creates accidental overwrites on the wrong record. Every automated write-back must use the record ID as the primary key.
- Setting required fields at creation without backfilling. Adding a required field to a form or stage transition does not fix the existing records that lack it. Backfill the historical population before enforcing the new rule.
- Auto-merging medium-confidence matches. Fuzzy name plus company matches have a meaningful false-positive rate. Auto-merging them at scale destroys history and creates support tickets. Queue them for human review.
Red flags during cleanup
- Duplicate rate spikes after a write-back run: the write-back created new records instead of updating existing ones.
- High volume of new imports bypassing validation: someone found a workaround or the validation rule has a gap.
- Bounce rate increases after an enrichment refresh: the enrichment provider’s email data is stale or low quality for your segment.
Recovery steps
If a bad merge or write-back runs at scale, your CSV backup from the pre-cleanup export is the rollback. Restore the affected records from the backup, document what went wrong, and fix the rule before re-running. For partial damage, use the CRM’s audit log to identify which records changed and when.
Five minutes of spot-checking catches systematic errors before they affect hundreds of records.
How an integrated platform reduces CRM decay over time
The operational case for consolidating CRM, enrichment, and workflow automation in one platform is not about features. It is about eliminating the gaps where bad data enters and accumulates.
Every time data moves between disconnected systems, there is a risk of duplication, field-mapping errors, and validation gaps. A contact imported from a marketing tool into a CRM via a flat-file export bypasses every validation rule the CRM enforces on web forms. A deal updated in a spreadsheet and synced back overwrites the CRM’s version without an audit trail. These are the structural causes of CRM data decay, and they are much harder to prevent with point solutions than with a unified platform.
Operational advantages of a consolidated approach
- Single source of truth. One record per contact, account, and deal, updated in real time by every team that touches it. No reconciliation between systems.
- Unified validation pipeline. Validation rules apply at every inbound touchpoint: web form, API write, manual entry, and import. No gaps.
- Centralized audit logs. Every field change, merge, and write-back is logged in one place with a timestamp and user attribution. Debugging is fast; compliance documentation is automatic.
- Consistent enrichment triggers. Enrichment fires on the same event regardless of how the record entered the system. No records fall through the cracks because they came in through a non-standard path.
Fewer syncs between systems means fewer opportunities for duplicates to form. Faster re-enrichment on new records means the data is current when it matters most, not three months later after the next quarterly refresh.
Pro Tip: When evaluating any platform for CRM data management, check whether it exposes audit logs and programmatic validation at every inbound touchpoint, not just on manual entry. That coverage gap is where most decay originates.
A RevOps perspective on running a successful CRM cleanup
The procedural steps in this playbook are the easy part. The hard part is getting the sales team to care.
Reps do not resist data hygiene because they are lazy. They resist it because they have never seen it pay off for them personally. The first time a deal gets misrouted because the account owner field was blank, that is another one. The cleanup earns buy-in when it visibly fixes problems the team already feels.
Start with wins that are fast and visible. A quick dedupe pass on active pipeline records takes a day and immediately removes the confusion of two reps working the same account. A bounce-rate drop after email verification shows up in the next campaign report. These early wins build the credibility to ask for the harder changes: required fields, picklist discipline, and the weekly hygiene review.
On required fields specifically: keep the list ruthlessly short. Every field you mark required at record creation is a field reps will game with placeholder values (“N/A,” “Unknown,” “test@test.com”) to move past the gate. Three to five required fields per object, enforced at stage transitions rather than creation, is more effective than ten fields enforced at entry.
The incentive alignment problem is real. Sales wants speed; operations wants accuracy. The resolution is not a policy. It is showing sales that clean data routes their leads faster, scores their accounts more accurately, and gets their emails delivered. When hygiene helps reps hit quota, they stop fighting it.
Manaxo keeps your CRM data clean without the manual overhead
Clean data is the prerequisite for reliable CRM automation. But maintaining it manually across disconnected tools is exactly the kind of recurring overhead that eats RevOps capacity. Manaxo’s all-in-one platform addresses this at the structural level.

Manaxo combines CRM, workflow automation, analytics, and enrichment triggers in one unified system. Validation rules fire at every inbound touchpoint. Merge logs are centralized. Enrichment workflows run on triggers you define, not on a manual quarterly sprint. For SMBs and mid-market teams that cannot afford a dedicated data engineering function, that consolidation is the practical alternative to a stack of point solutions that each require their own maintenance.
The CRM benefits for growing companies extend well beyond contact management: unified customer records, automated lifecycle tracking, and governance controls that keep data reliable without constant manual intervention. See how Manaxo fits your operation at Manaxo, or start with a free trial to run your baseline audit inside a clean, integrated environment.
Sources
The following sources informed this playbook and are worth consulting for deeper dives into specific steps:
- CRM Data Hygiene: The No-BS Guide to Clean Data
- CRM data hygiene playbook
- CRM Data Quality: The AI Cleanup Playbook
- How to Clean Your CRM Data: A Step-by-Step Guide for RevOps | Cleanlist
Recommended


